The dependency you can't draw
A supplier list says who you buy from. A dependency map shows what breaks, what it takes down and what you switch to when a critical service fails.
What it is
Last Thursday evening, a few minutes after six, the London market's universal tool stopped working. Microsoft 365's servers began a cascade failure: some went down, the survivors took their traffic, and they buckled under the load. Every attempt to bring machines back overnight was met by a flood of reconnecting users that knocked them over again. By Friday morning the outage had run past fourteen hours, and the market spent the day on phones, texts and whatever had been drafted in advance. One broker, trying to get a lease document to a client's solicitor, put the whole situation in a sentence: "Obviously no one has faxes anymore."
The outage was not a cyberattack. Microsoft has said there was no sign of malicious activity, and the early loss estimates, $300m to $500m globally, reflect the awkward truth that most business interruption wordings do not pay for a non-malicious technical failure, and most firms cannot prove a loss of net profit from a missing inbox. So the insurance market will survive Friday the 13th cheaply. That is precisely why the week deserves more attention than it will get. The event was not a test of cyber cover. It was a test of something the market never consented to be tested on: whether firms can draw their own dependencies.
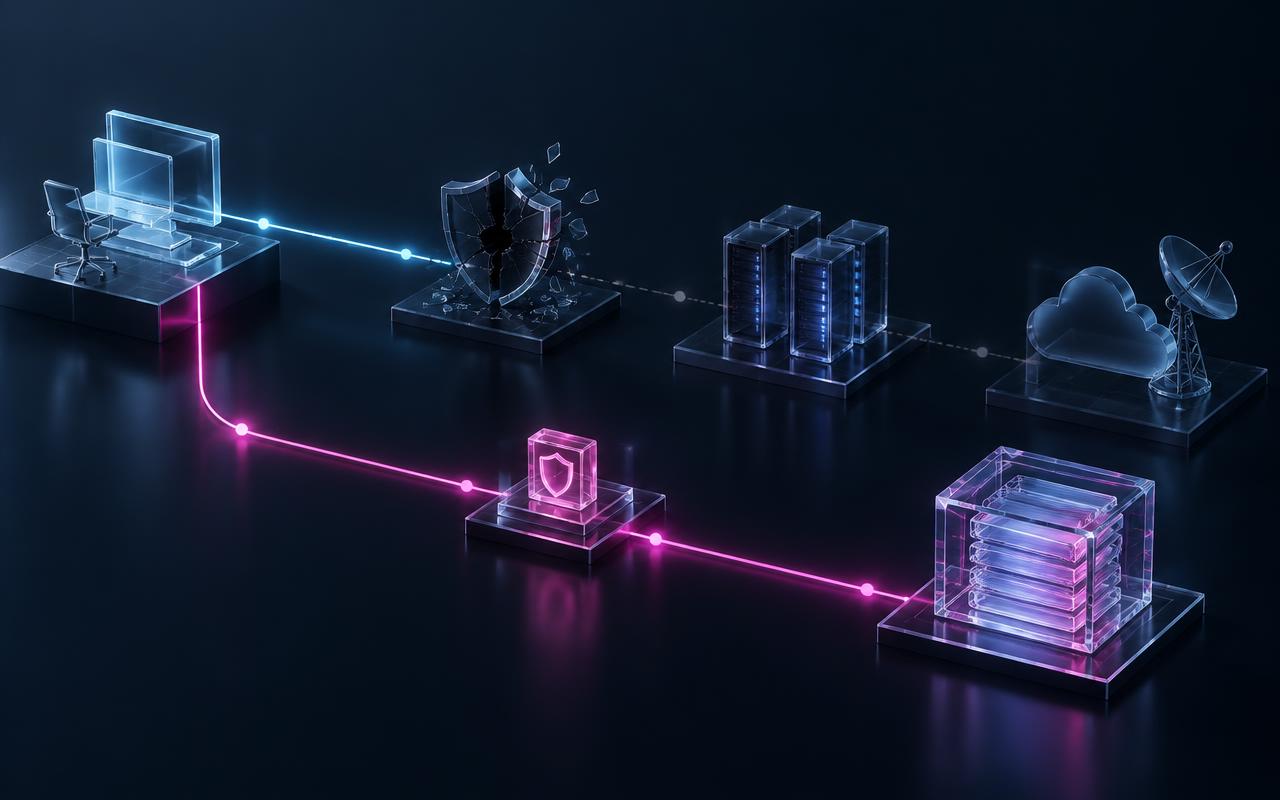
The uncomfortable finding is that most cannot. The chain that failed was not exotic: an underwriter's screen, an authentication service, a server farm, an identity provider, a mail platform. Every link was a household name, and almost nobody had the chain drawn end to end before Thursday. What firms had instead was a list of suppliers and a general sense that everything ran on Microsoft. A list tells you who you buy from. A drawing tells you what breaks when they break, what it takes down, and what you switch to. Friday the 13th was what happens when the distinction is tested in production.
Why it matters now
Because the world the London market operates in has quietly stopped treating this as a private matter. Since 13 July, Microsoft Ireland Operations Limited has been one of four critical third parties to the UK financial sector, alongside AWS, Google Cloud and Oracle, under direct oversight by the Bank of England, the PRA and the FCA. An outage of this length is an early test of that regime, and the supervisors will not be asking Microsoft alone how it happened. They will be asking every firm that relies on it how it stayed within its own impact tolerances under the operational resilience rules, and what it did while the service was down. The firm that can produce the drawing, the tolerance, and the log of workarounds will have answered before the question finishes. The firm that cannot will be describing its outage response from memory, and memory is not a regulatory artefact.
The second reason is that the outage landed on a market whose technology strategy just became, formally, every firm's own problem. Blueprint Two was shelved in March, and the read from the people who implement this stuff is blunt: the premium and accounting settlement platforms at the core of the market are old, complex, and not API-based, with no real alternative at the moment. Delegated authority, roughly 40% of the market by premium, still runs on bordereaux arriving in inconsistent formats. When the central programme died, the coordination problem became a firm-by-firm problem, and Friday showed what that means in practice. The firms that fared best were the ones that could name, in advance, what they depend on and what they would do without it.
The third reason is the workaround. In a crisis, people improvise, and improvisation without a plan becomes its own risk. On Friday, staff moved client files to personal email and messaging apps, creating data protection problems that will outlast the outage, while fraudsters worked the disruption with fake IT-support calls and changed bank details. The firms that had thought about their workarounds in advance, and had agreed with counterparties how cover would be confirmed while email was down, traded through the day. The firms that had not discovered their workarounds live, in front of clients. A workaround you design is a continuity plan. A workaround you improvise is a second incident.
What firms should do
Draw the chain, not the list.
For every critical business service, produce a map that shows each component it runs on, each interface between components, and each third party behind a component, down to the level of the authentication and routing services that failed on Friday. The test is simple: could a person new to the firm pick up the drawing and say, within minutes, what breaks if this link fails and what the alternative is? If not, it is a list, not a drawing.
Test the tolerance against last week.
The outage ran past fourteen hours. Most firms' impact tolerances for email-dependent services sit inside that number, which means Friday was, for most of the market, a real breach of tolerance that nobody had to report because the cause sat with a third party. Run the exercise honestly: which of your stated tolerances would this event have broken, and what would you have had to do if the cause had been yours? The answer tells you where your tolerance statements are fiction.
Govern the workarounds before you need them.
Write down, in advance, what the market-facing fallback is for each critical service: how binders are confirmed without email, how premium instructions move, how claims notifications land, which phone numbers are the known ones for payment changes. Then make the workaround itself a governed process with a log, because the log is the evidence, to clients, to counterparties, and to supervisors, of what you did while the service was down.
Keep the record past the recovery.
Firms that later face a claim, a dispute or a supervisory question about the outage will be helped by a simple log of when systems failed, what workarounds were used, and when service returned. The firms that kept one this week will be the ones whose accounts of the event survive contact with a lawyer or a regulator. The rest will be arguing from recollection against a document.
The opmodal perspective
This is what the Architecture Canvas was built for. The Canvas maps systems, interfaces, controls and reports, and the dependencies between them, so that a firm can see, on one drawing, what touches what. The discipline is the same one the market applies to risk: you cannot manage an exposure you cannot see, and an undocumented dependency is an exposure with no owner. The Canvas treats the dependency map as a living artefact, reviewed and re-certified like a policy wording, because a drawing that is made once and never touched is exactly what failed this week: a map that no longer matches the territory.
The week's deeper lesson is about the difference between the two states. The firm that maintains its dependency map before the outage spends the outage executing the plan. The firm that does not spends the outage discovering the problem. Compare States, applied to your own operating model, is the honest version of that exercise: current state, the chain as it actually runs today, target state, the chain with the missing links drawn and the tolerances attached, and the delta between them as the work programme. Friday the 13th was the market running that comparison live, for free, with the regulator watching. The firms that run it in advance will be the ones whose next outage is a footnote. The rest will be tested again, at a worse moment, and the drawing either exists or it does not.